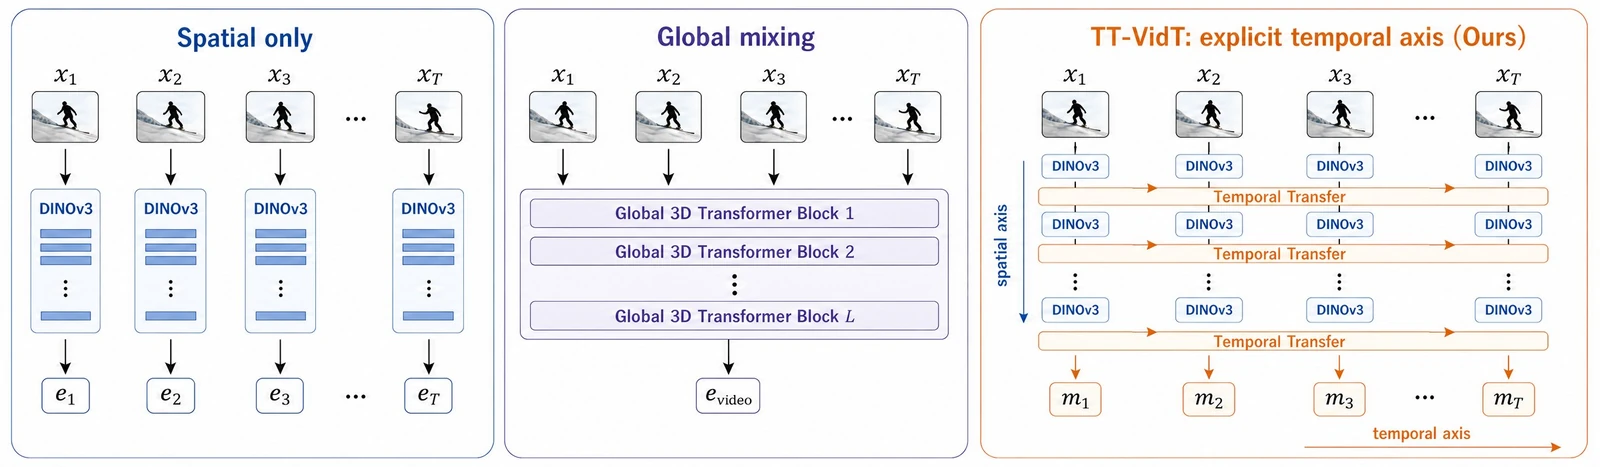
TT-VidT: Decoupling the Temporal Axis for Efficient Motion-Centric Video Pretraining
A motion-centric video encoder that separates appearance from temporal dynamics using compact motion tokens. Temporal Transfer layers and Diff Compression improve motion-sensitive recognition with about half the encoder FLOPs of VideoMAE, V-JEPA 2, and DisMo.